New Dataset Takes Aim at Subjective Misinformation in Earnings Calls and Other Public Hearings
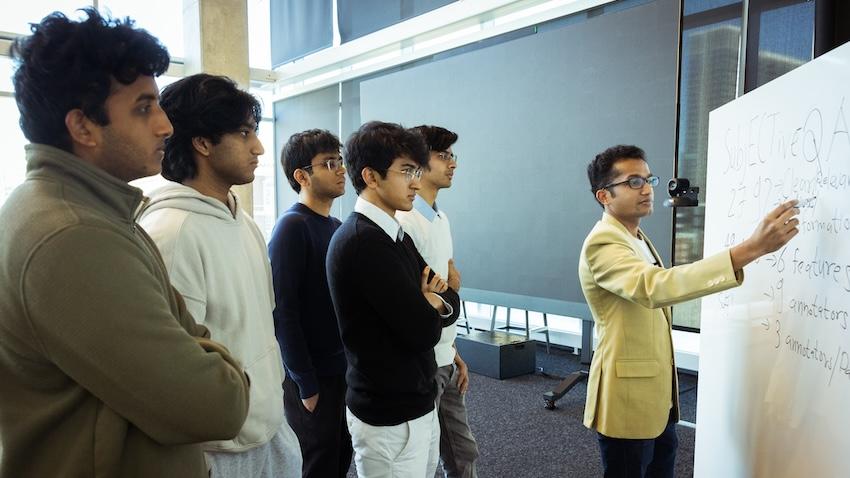
Georgia Tech researchers have created a dataset that trains computer models to understand nuances in human speech during financial earnings calls. The dataset provides a new resource to study how public correspondence affects businesses and markets.
SubjECTive-QA is the first human-curated dataset on question-answer pairs from earnings call transcripts (ECTs). The dataset teaches models to identify subjective features in ECTs, like clarity and cautiousness.
The dataset lays the foundation for a new approach to identifying disinformation and misinformation caused by nuances in speech. While ECT responses can be technically true, unclear or irrelevant information can misinform stakeholders and affect their decision-making.